
Core Announcement: Zhenwu V900 Release and Timeline
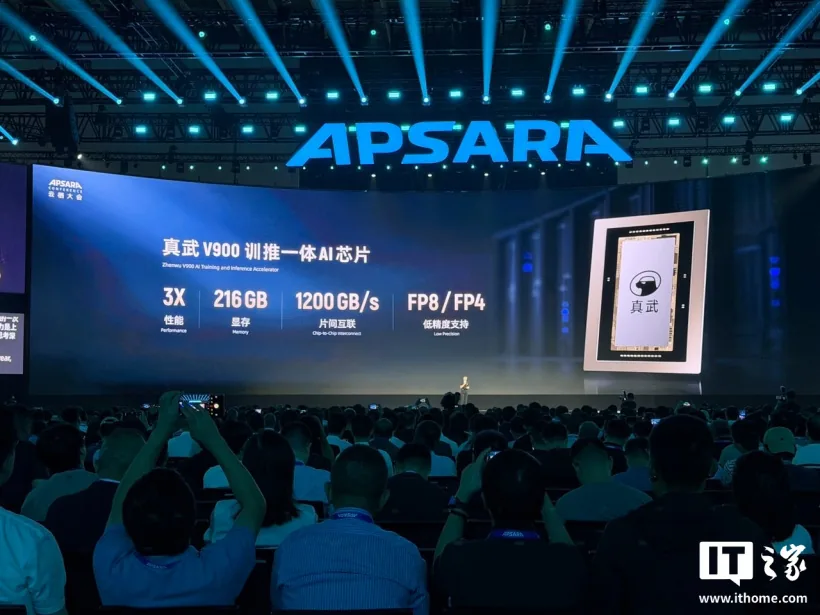
Alibaba’s Pingtouge unveiled the Zhenwu V900—the company’s strongest domestic AI chip—at the 2026 Cloud Computing Conference (Cloud Expo) on September 22. Key facts:
- Release date: September 22, 2026 (day one of the conference)
- Chip category: Training-inference unified AI chip (supports both model training and inference)
- Hardware specs: 216GB VRAM, 1200GB/s inter-chip interconnect bandwidth, FP8 and FP4 precision
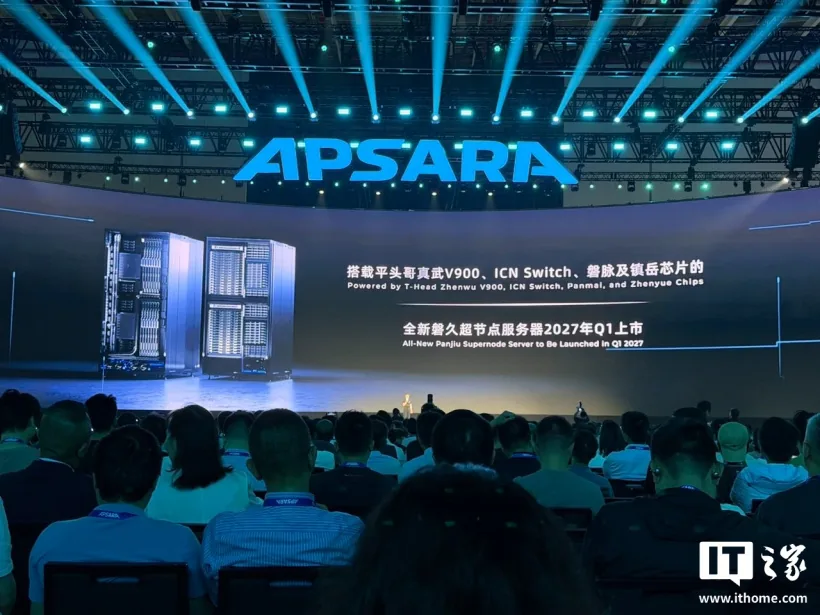
- Product release:磐久 (Panjiu) hyper-node server搭载 Zhenwu V900 will ship in Q1 2027
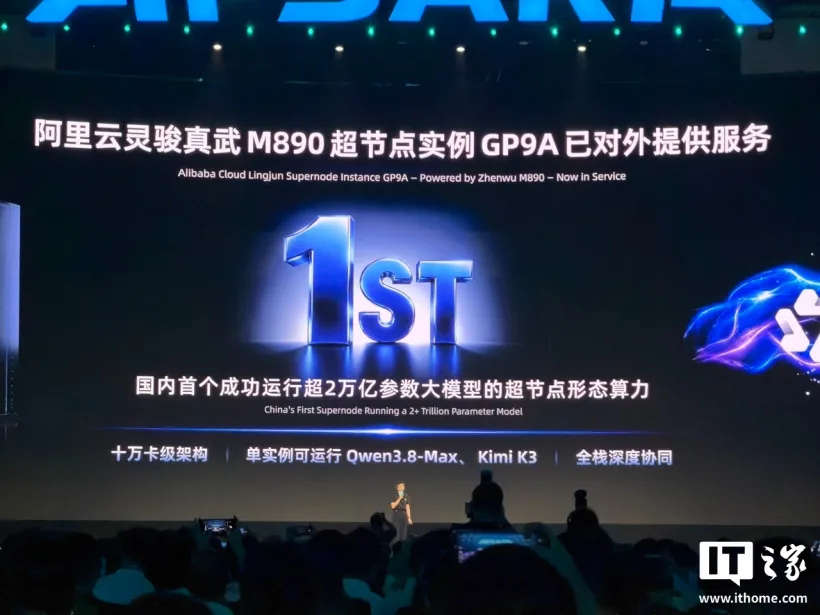
- Transitional product: The灵骏 (Lingjun) GP9A instance with Zhenwu M890 is already available
- Next-gen plan: Zhenwu J900 scheduled for Q3 2028, featuring a new in-house parallel computing architecture
The V900 represents a significant leap in domestic AI compute capability under a unified architecture.
Technical Details and Strategic Positioning
Zhenwu V900 delivers threefold performance over its predecessor, Zhenwu M890, accompanied by 216GB VRAM capacity and 1200GB/s inter-chip interconnect. It supports both FP8 and FP4 low-precision floating-point operations.
An notable strategic choice is the training-inference unified design. This differs from the typical industry approach of deploying separate dedicated training and inference chips. A single chip handling both workloads reduces deployment complexity in large-scale clusters and mitigates VRAM fragmentation—a common pain point where training and inference have conflicting memory management requirements, leading to underutilized resources.
Alibaba Cloud’s Lingjun GP9A instance, built on Zhenwu M890 hardware, reportedly became the first在国内 to successfully run a large model exceeding 2 trillion parameters via a hyper-node architecture. This successful deployment provides a validated foundation for the V900’s engineering readiness.
Ecosystem Synergy Across Chips
This launch encompasses more than a standalone chip—it introduces a hyper-node hardware stack:
- Zhenwu V900: Primary AI compute chip (training-inference unified)
- ICN Switch: Networking chip enabling the 1200GB/s inter-connect
- Panmai: Storage-related chip supporting the 216GB VRAM configuration
- Zhenyue: Server management/control chip
Together, these components form the full-stack, in-house developed system underlying the Panjiu hyper-node server, reflecting Alibaba’s integration strategy spanning compute, interconnect, storage, and control.
Zhenwu Series Generational Comparison
| Version | Release | Relative Performance | VRAM | Inter-Connect | Precision | Server Availability |
|---|---|---|---|---|---|---|
| Zhenwu M890 | 2026 (earlier than V900) | 1x | Not disclosed | Not disclosed | Not disclosed | Lingjun GP9A available |
| Zhenwu V900 | Sept 22, 2026 | 3x | 216GB | 1200GB/s | FP8/FP4 | Q1 2027 |
| Zhenwu J900 | Expected Q3 2028 | Not disclosed | Not disclosed | Not disclosed | Not disclosed | Post-2028 |
Deployment Recommendations
Early adopters needing 2-trillion-plus parameter model training or inference can use the existing Lingjun GP9A instance (M890) as an interim solution.
Wait-and-see with timing:Enterprises planning large AI infrastructures within the next two years should target the Q1 2027 Panjiu server launch. The unified-architecture V900 may offer lower long-term operational complexity if performance targets materialize.
Rationale for delayed adoption: For workloads satisfactorily served by current multi-GPU setups or for models below the hundred-billion parameter threshold, monitoring comparative pricing and benchmarks post-V900 launch remains prudent.
Final Note
Domestic AI chip development is shifting from component-level breakthroughs toward integrated system optimization. Should Zhenwu V900 deliver on its promised performance, its unified-architecture approach could reshape competition in large-scale AI infrastructure.