
GPT-6 Astra Tops Bilibili AI Arena, Chinese Models Dominate Top 5
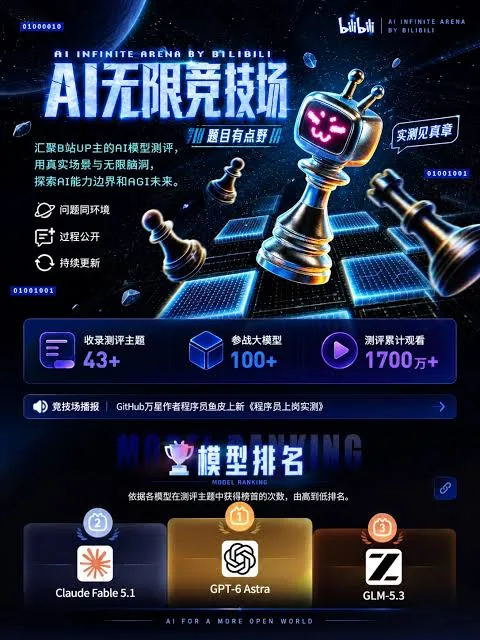
On September 20, Bilibili officially launched the “AI Infinity Arena” large model ranking system, unveiling its first round of evaluations. The测评 system aggregates real-scenario assessments by UP artists across platforms, covering code, reasoning, collaboration, and knowledge tasks.
Key highlights:
- GPT-6 Astra secured the top position, winning first place in 10 UP artist evaluations (rank-count champion)
- Chinese models occupy three of the top five spots, demonstrating strong domestic competition
- Evaluation spans mainstream models: DeepSeek, Kimi, ChatGPT, Claude, Gemini, Doubao, Qwen, Hy, MiniMax
Unlike conventional benchmark assessments, the “AI Infinity Arena” imposes no constraints on topics or evaluation dimensions. UP artists submit autonomous case studies based on real workflows, professional applications, and creative challenges—creating直观 comparisons of actual performance differences.
Community-Driven Testing Gains Industry Attention
Bilibili’s evaluation methodology breaks from traditional AI assessment practices that rely solely on standardized tests. Artists evaluate models according to their specific creative needs: code generation quality, reasoning chain completeness, and对话 coherence across multiple interactions.
The key advantage: results reflect real-world usage rather than exam preparation, avoiding overfitting to benchmark datasets. GPT-6 Astra’s top position stems from comprehensive evaluations by multiple UP artists across diverse scenarios, not just one technical metric.
Notably, while GPT-6 Astra claims the summit, Chinese models show promising differentiation: certain lead in Chinese content generation fluency, others excel in code comprehension or structured data handling. This niche differentiation forms a viable differentiation path for domestic models.
Open System Enables Real-Time Industry Monitoring
The “AI Infinity Arena” features publish-always-updating capabilities—UP artists can submit new evaluations anytime, with rankings updating automatically. This design establishes the system as a real-time monitoring lens for model evolution.
Industry observers note that community-driven evaluation systems complement institutional benchmarks. As new models like GPT-6 Astra rapidly iterate, community tests capture stability and compatibility issues beyond lab data.
Reader Recommendations
For developers: Use the ranked models within specific task categories (e.g., code-related rankings) for preliminary selection.
For enterprise procurement teams: Treat community results as POC inputs but supplement with customized business testing.
For creators: The comparative display helps identify suitable AI assistants based on documented capability gaps.
Final Thoughts
Bilibili’s AI Infinity Arena marks a shift from closed-lab assessments to open, community-based evaluations. This model tests both real capability and evaluation objectivity—no model can maintain “paper leadership” long under diverse autonomous UP artist challenges. If more platforms adopt this approach, industry AI capability assessments may grow increasingly rational.