
Core Event and Availability
A systematic technical guide on Multi-Agent Collaboration Systems (Chapter 28) was published by the稀土掘金 developer community, addressing large-scale AI collaboration challenges. No commercial product release date or pricing information is included; this is open-source technical documentation with reusable architectural patterns.
Key implementation details:
- Target scenario: Industry report generation requiring coordination among research, data analysis, writing, and review stages
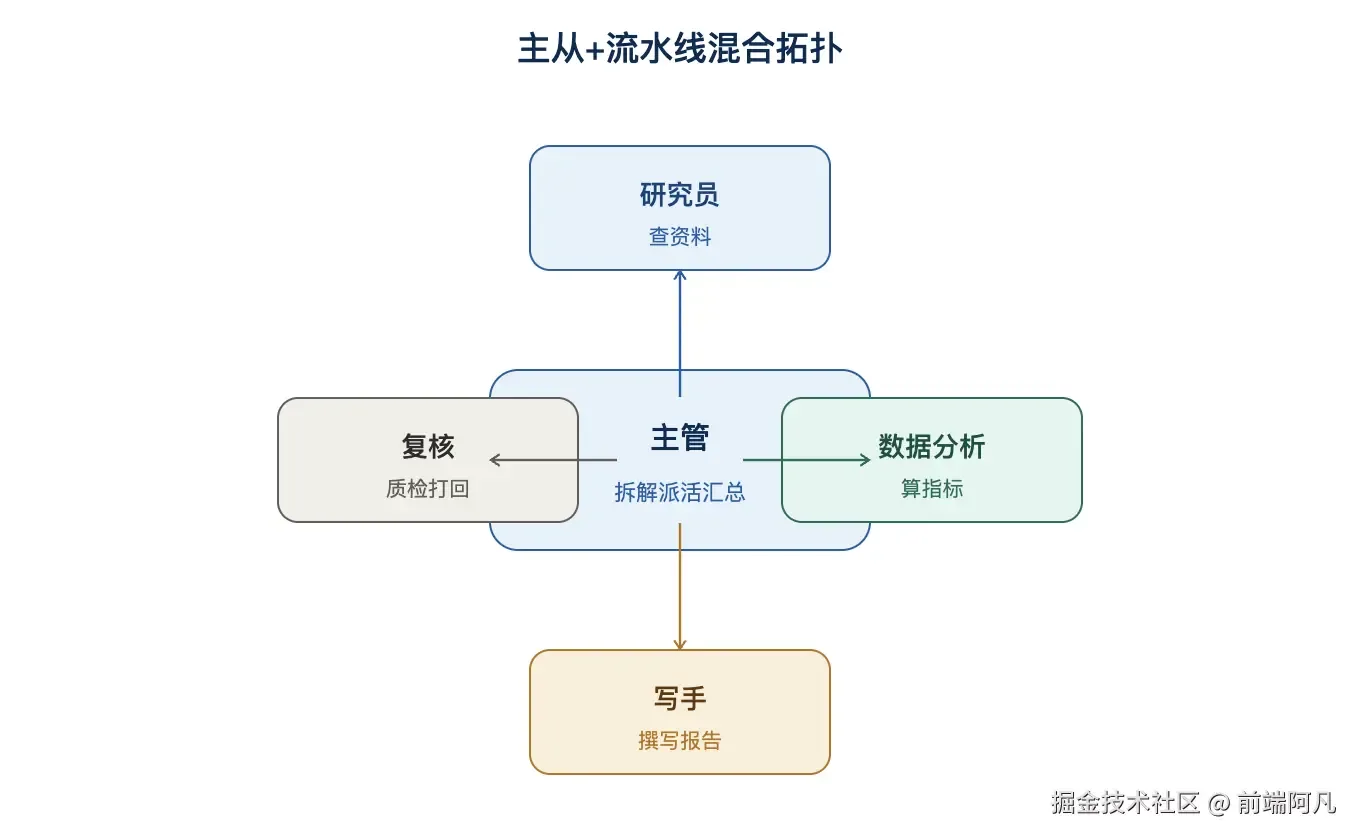
- Topology: Supervisor-worker master-slave structure combined with researcher/analyst/writer/reviewer pipeline
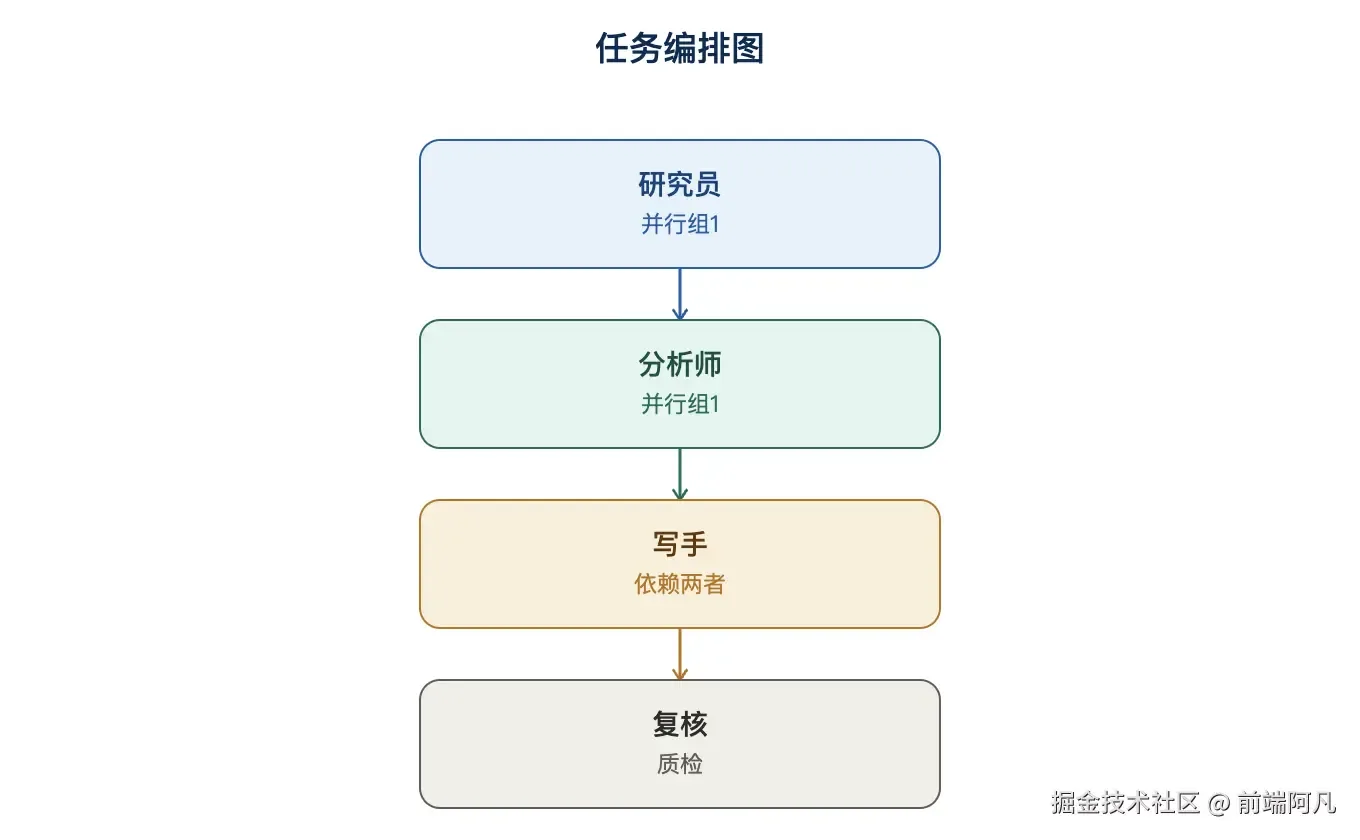
- Orchestration: Async scheduling via task dependency graph using
depends_onrelationships - Open status: Pseudocode and structural diagrams only; no runnable codebase provided
Topology Design and Structured Communication
The solution addresses three fundamental limitations of single-Agent systems in complex workflows: role specialization separation, context isolation, and parallel processing benefits. When tasks require fundamentally different tools (e.g., search for researchers vs. calculators for analysts) and massive context windows, mixed topologies outperform monolithic approaches.
The supervisor handles task decomposition, delegation, and final synthesis. Four worker agents sequentially process outputs: researchers produce factual summaries, analysts compute structured metrics, writers generate reports from these structured inputs, and reviewers perform quality control. A key reversal in this design is that the reviewer serves as a quality gate—not a content producer—preventing the logical conflict of “being both player and referee.”
Communication follows a structured-protocol model, rejecting unstructured chat. Each worker outputs only spec-compliant JSON: researchers return {"findings": [...], "summary": "..."}, analysts return {"metrics": {...}, "trend": "..."}. This契约-based exchange eliminates noise contamination. The orchestration executes in three waves: Wave 1 runs researchers and analysts in parallel via asyncio.gather, Wave 2 processes the writer only after both inputs are ready, and Wave 3 runs reviewer quality control, re-triggering writer revision when non-compliant—creating a closure loop.
Context Isolation and Observability
Context isolation is the system’s foundational principle. The “only-feed-what-is-necessary” strategy ensures engineers control precisely what each worker receives: researchers see only task goals, analysts receive raw data, and writers consume only structured JSON outputs—not raw chat history. Three-layer isolation is implemented: input isolation (precise feeding), output isolation (JSON-only exchange), and state isolation (independent worker execution).
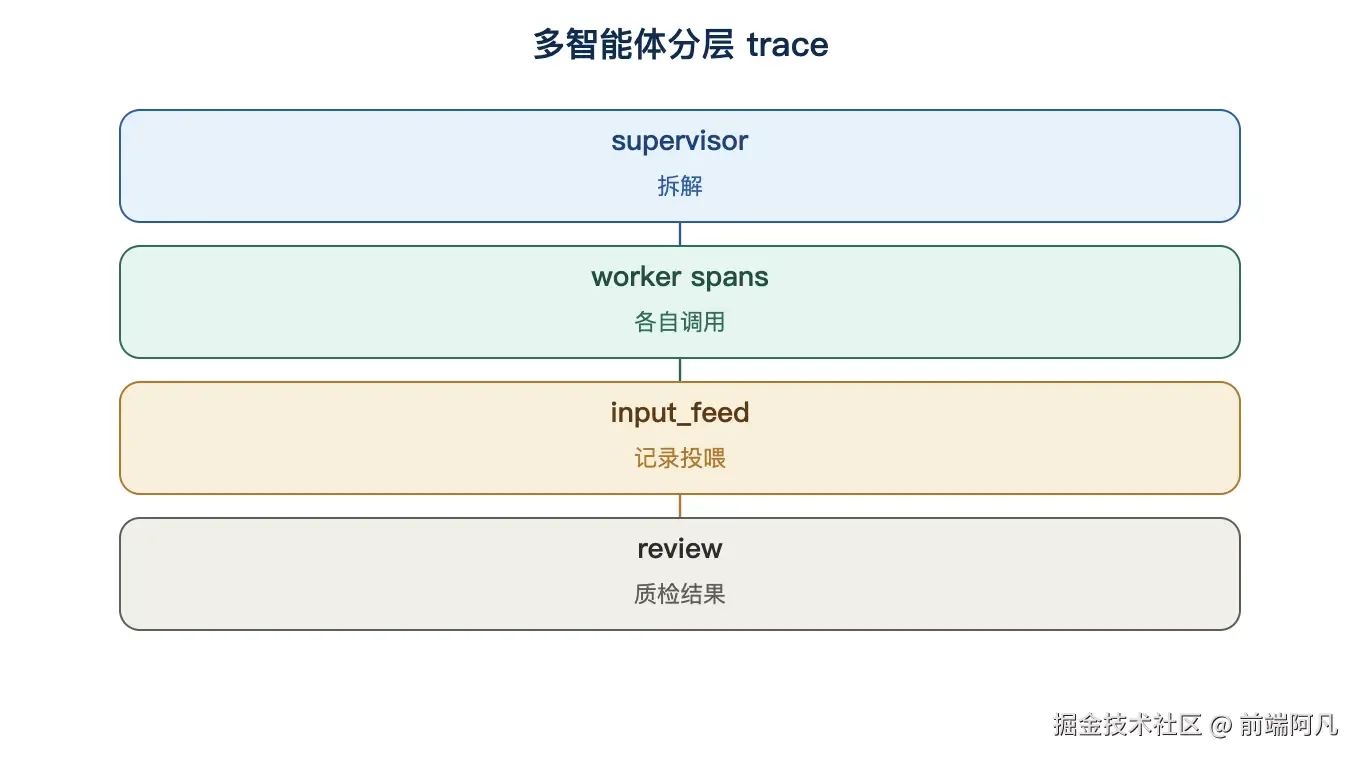
Observability uses hierarchical tracing with each Span logging agent type, processing type (LLM/tool call), and crucially input_feed (exactly what that worker saw). When reviewers flag “missing market size source”, traces immediately verify whether the writer received raw reports or only the analyst’s structured JSON—this is the only reliable debug method for context contamination. As noted: no trace means no debug capability, especially given the 10x complexity increase in multi-agent debugging.
Failure Localization and Efficiency Metrics
Five failure patterns are documented with fixes:
- Context pollution between workers → feed isolation + structured exchange
- Review loops causing task deadlock → 2-attempt limit before human takeover
- Writers hallucinating data → writer role stripped of data access; reviewers verify sources
- Unauthorized tool usage → RBAC + tool whitelisting
- Lower efficiency than single-Agent → evaluate collaboration metrics; revert if unnecessary
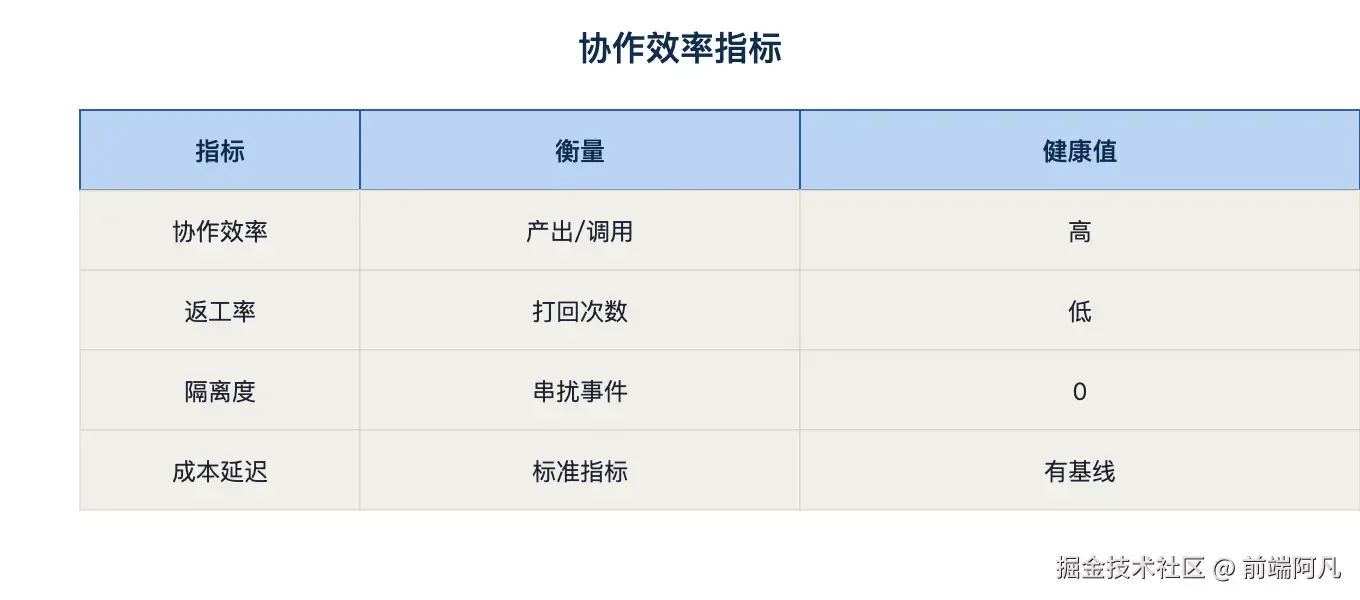
协作 efficiency metrics supplement traditional four-dimension indicators (performance, stability, cost, quality). Systems must monitor: actual vs. theoretical parallel ratio (whether parallel groups execute concurrently) and rework rate (writer revision frequency). Low efficiency signals that task simplicity doesn’t justify multiple agents.
Reader Deployment Guidance
- Deploy now if: Your workflow naturally separates into distinct stages (collection → analysis → drafting → review) with different tool requirements, and you can implement tracing infrastructure.
- Wait if: Your task is linear and simple (e.g., single-pass drafting), or your team lacks foundational observability—this guide explicitly warns: “more agents is not better.”
Final Note
The industry report case proves multi-agent systems aren’t about agent quantity—they’re about mapping task complexity to engineering rigor. True value lies not in adopting the hype but in designing clean communication protocols and isolation boundaries that make complex coordination predictable, measurable, and debuggable.