
Grok 4.8 and 4.9 Timeline, Parameters Confirmed
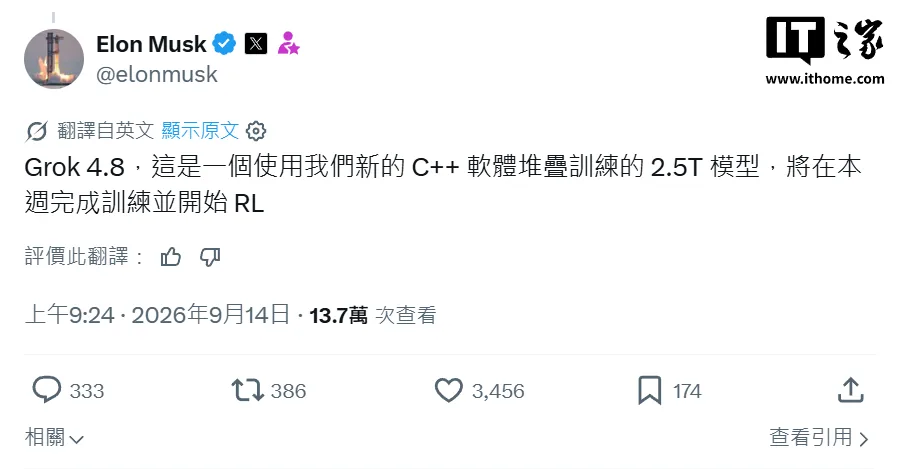
Elon Musk, CEO of xAI, disclosed key details on X platform on September 14:
- Grok 4.8: 2.5 trillion parameters, trained with a new C++ software stack, will finish training this week and enter reinforcement learning (RL) phase
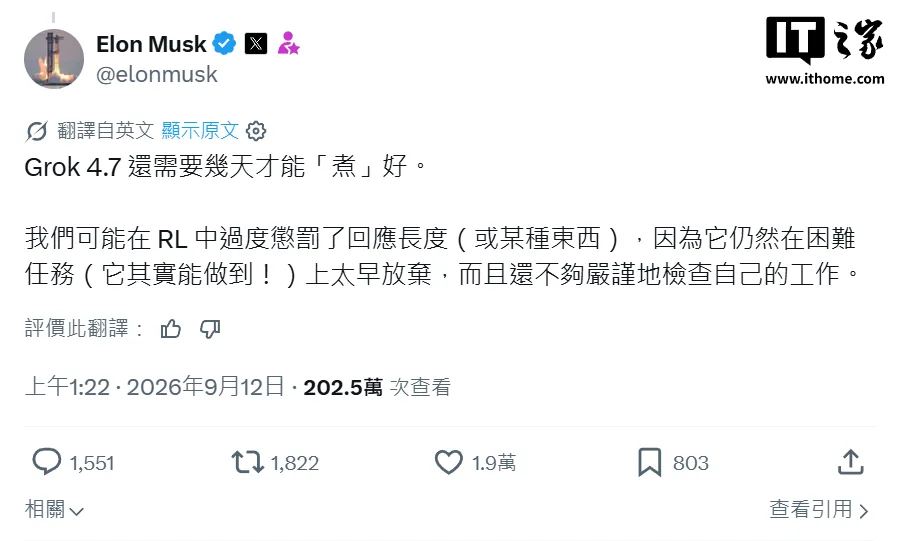
- Grok 4.7: Originally scheduled for September 12, actually delayed several days; delay attributed to overly harsh length penalties in RL causing premature task abandonment and poor self-checking
- Grok 4.9: Musk stated its capability may match OpenAI Astra (GPT-6) or Anthropic Fable
- Grok 5: In response to a follower’s question, Musk explicitly stated AGI (Artificial General Intelligence) realization will depend on Grok 5
All timeline and parameter data derive from Musk’s public replies on X.
Model Capability Benchmarks and Technical Details
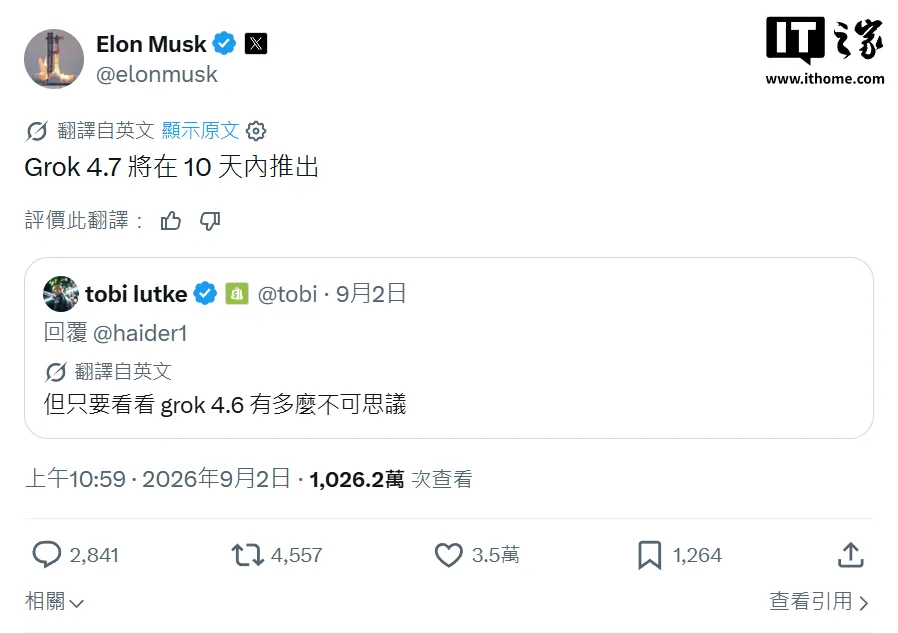
Musk indicated Grok 4.7’s capability roughly matches Anthropic Opus 5.0 (not 5.1), with multimodal performance still requiring fixes. He noted Grok 4.8 will bring significant improvements, directly tied to its new C++ training stack—C++ offers advantages over Python in inference speed and memory management, critical for ultra-large-scale model training.
A notable contrast: although Grok 4.7 already belongs to the top-tier model class (matching Opus 5.0), it exhibits明显 engineering-era flaws (overly short responses, inadequate self-checking), revealing that closing the gap between theoretical capability and stable real-world output remains a significant challenge. Reinforcement learning can enhance model performance, yet poor tuning may introduce new behavioral issues.
| Model Version | Parameters | Training Status | Capability Benchmark | Multimodal Performance |
|---|---|---|---|---|
| Grok 4.7 | Undisclosed | Launched | Anthropic Opus 5.0 | Needs fixing |
| Grok 4.8 | 2.5 trillion | Training, RL pending | Undisclosed, Musk says “significant improvement” | Undisclosed |
| Grok 4.9 | Undisclosed | Not started | OpenAI Astra / Anthropic Fable | Undisclosed |
| Grok 5 | Undisclosed | Not mentioned | Musk says “may surpass everything” | Undisclosed |
Reader Recommendations
- For most stable current performance: continue using Grok 4.7; its core capability is industry top-tier, and multimodal issues do not affect text reasoning tasks
- For those accepting early-tech risk: monitor Grok 4.8’s RL phase starting this Friday; its improvements may include longer, more rigorous reasoning chains
- For AGI exploration interest: Grok 5 is the milestone to track, though no release timeline exists; maintain interest without near-term expectations
Final Word
Ultra-large parameter counts are becoming the standard path for top models, yet Grok’s repeated references to “engineering fixes” reveal a market reality: model scale and practical stability are not linearly correlated. If xAI can sustain its rapid iteration pace, it may accelerate practical applications across the entire industry.