
Core Event: Ultrafast API Expansion Expected at DevDay
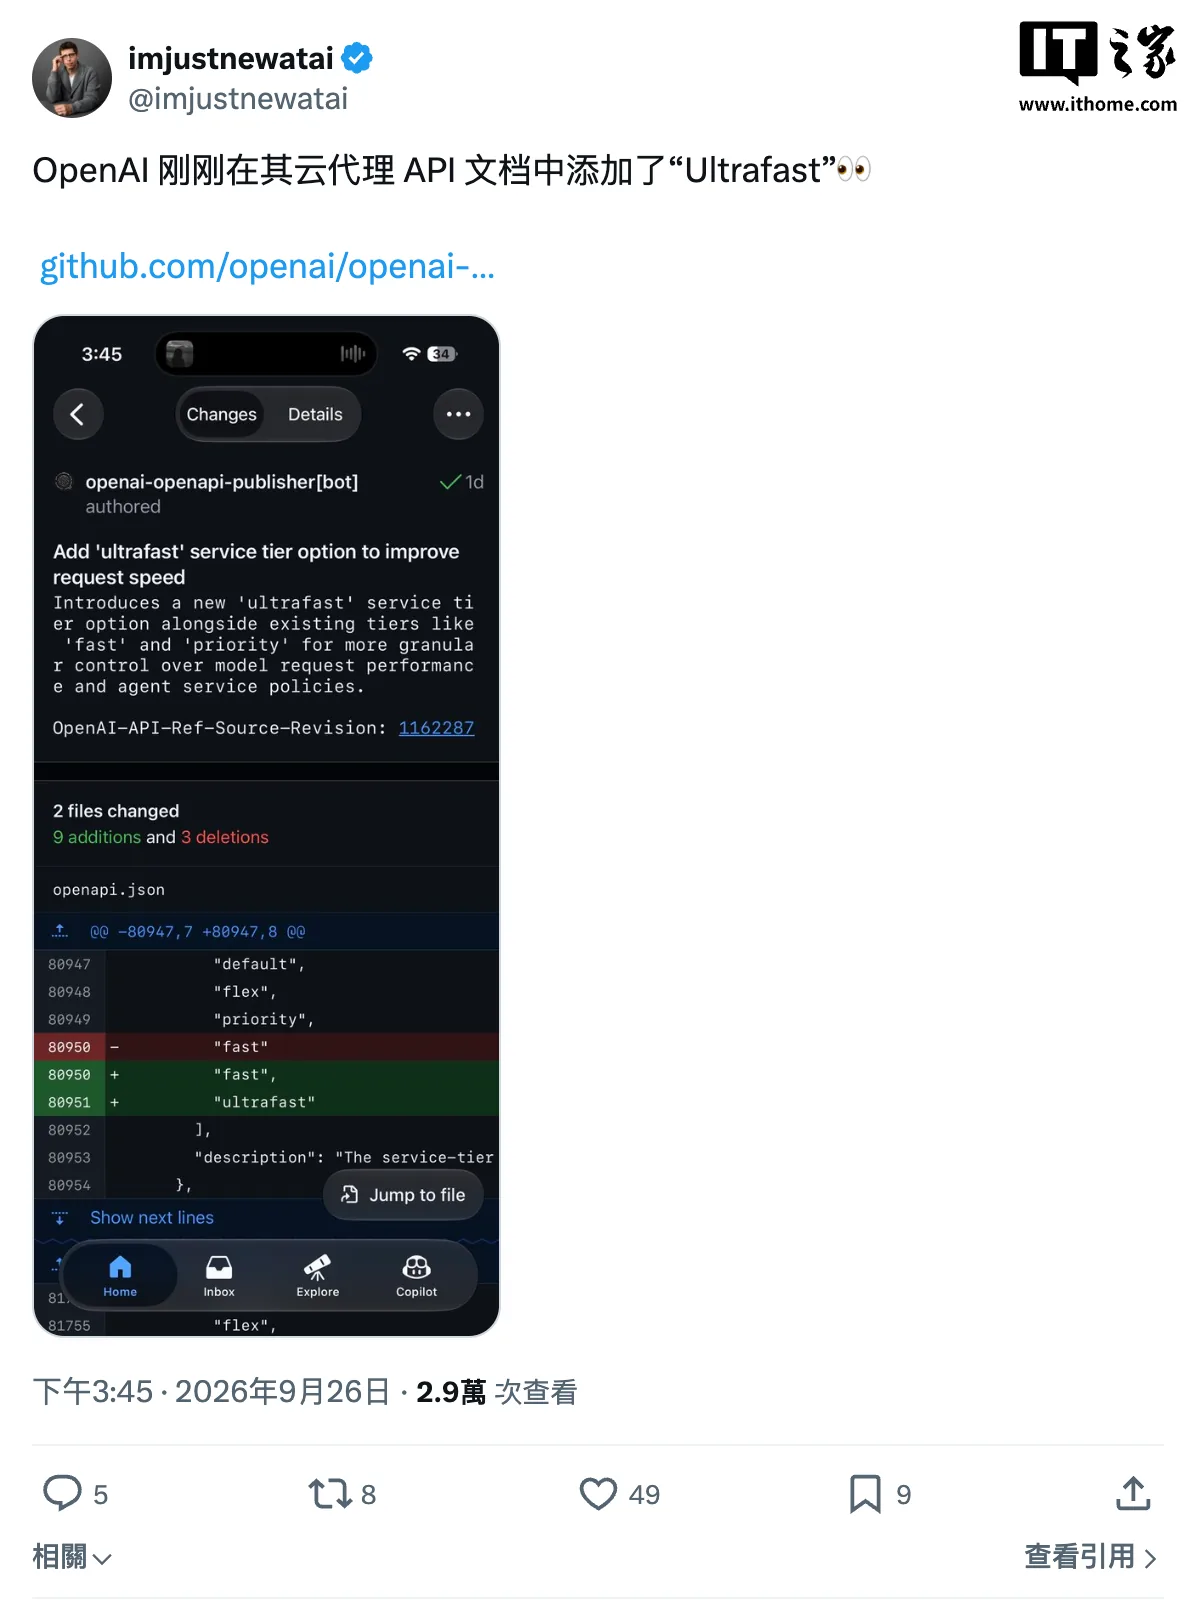
OpenAI has added Ultrafast API documentation to its Platform and API references, signaling an imminent expansion of the feature’s availability, according to IT之家’s September 27 report. The DevDay event scheduled for September 29 is the likeliest venue for an official announcement.
Key hard facts:
- Expected release time: September 29 at DevDay
- New version: Ultrafast mode powered by GPT-5.6 Sol
- Current status: Limited to select customers; hidden feature in Responses API Playground
- Output performance: Up to 750 tokens per second
- Speed improvement: Up to 14× faster than Standard mode
Technical Details: Speed Option and Hidden UI
The Ultrafast mode has entered preview, capable of outputting up to 750 tokens per second—a benchmark confirmed by OpenAI. A token represents the basic unit of text processed by the model; 750 tokens/second equals roughly 1-2 sentences per second in natural English, enabling near-instant responses.
OpenAI is preparing a new speed selector for its Responses API Playground, offering three tiers: Standard, Fast, and Ultrafast. At present, this selector remains hidden, indicating the feature is still in internal testing or limited rollout.
A notable contrast: A throughput of 750 tokens/second significantly exceeds many currently available Commercial models—typical enterprise LLM APIs operate between 50–200 tokens/second for inference for inference.
GPT-6 Compatibility: Critical Unknown
OpenAI has recently launched the GPT-6 family, including GPT-6 Sol and GPT-6 Astra. Importantly, no official confirmation exists regarding whether GPT-6 models will support Ultrafast mode upon release. Source materials explicitly avoid asserting compatibility.
The model ecosystem is in transition: GPT-5.6 Sol is the confirmed initial carrier for Ultrafast, while integration with GPT-6 remains unverified. Developers should budget time for compatibility testing post-announcement.
Comparison Table: Speed Tiers (Source-Based Only)
| Mode | Availability | Max Throughput | Compared to Standard | Note |
|---|---|---|---|---|
| Standard | Widely available | Baseline | Reference | Default option |
| Fast | Not yet clarified | Not disclosed | Not disclosed | Limited info |
| Ultrafast | Preview stage, limited access | 750 tokens/sec | Up to 14× faster | Expansion expected at DevDay |
Practical Recommendations for Developers
- Try now if eligible: Preview-invited developers can test Ultrafast in latency-sensitive use cases (e.g., real-time chat, frequent interactive prompts) until full rollout.
- Wait for GA if: You’re an individual dev or small team—avoid integration friction caused by hidden features or access restrictions.
- GPT-6 adopters: Hold architecture adjustments until OpenAI confirms Ultrafast support, as current documentation provides no indication either way.
Final Thoughts
Expanding Ultrafast access represents OpenAI’s aggressive push on inference speed—a shift that could pressure competitors to raise their latency targets. Whether this speed spike translates into sustainable, cost-efficient offerings remains the decisive factor for mainstream adoption.