
Snapdragon Summit Announces Breakthrough in On-Device Large Model Deployment
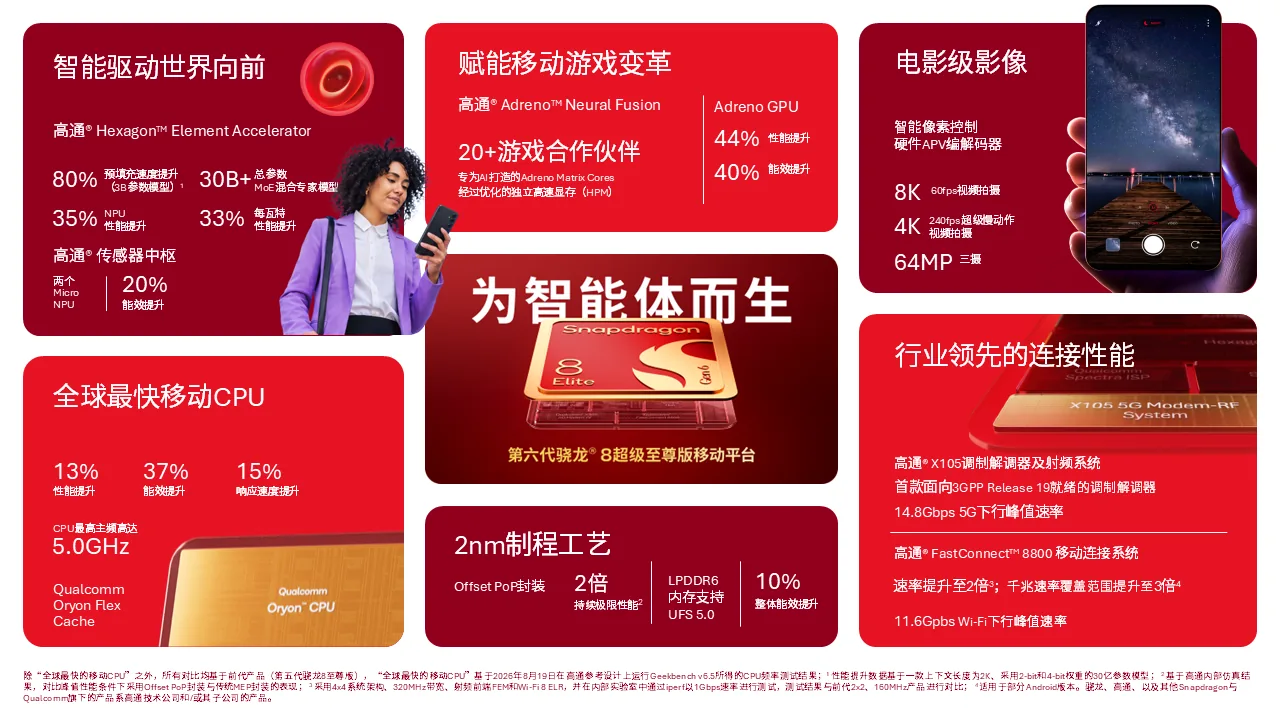
On September 22, 2026, local time in Hawaii (3:00 AM Beijing time on September 23), Qualcomm officially announced at the Snapdragon Summit that, based on the sixth-generation Snapdragon 8 Supreme Edition mobile platform, it has completed on-device AI model adaptation and inference optimization in collaboration with Step, Wuliang Huo, and Jiangbo Long. The core achievement is the stable operation of the StepEdge-Omni 30B-MoE model on smartphones, with a pre-fill throughput exceeding 330 tokens per second and a decode throughput exceeding 28 tokens per second.
The model has 30 billion parameters and employs a Mixture of Experts (MoE) architecture—activating only specific expert modules as required by each task, thereby controlling computational overhead while maintaining capability.
Technical Breakthrough: 50%+ Memory Reduction, Local Inference Becomes Reality
Deploying a 30-billion-parameter model on-device faces three challenges: inference compute power, memory bandwidth, and storage efficiency. The partnering companies achieved breakthroughs through three optimization dimensions:
- Inference Engine Optimization: Custom sparse activation paths tailored for the MoE architecture to reduce idle computation
- Heterogeneous Scheduling Strategy: Dynamic task allocation across CPU, GPU, and NPU resources
- Storage Architecture Refactoring: Reducing memory bandwidth pressure and improving data throughput
Crucially, the model runtime memory requirement is reduced by over 50% compared to industry-standard solutions, enabling on-device inference on smartphones. Qualcomm emphasized that this solution operates entirely offline, handling tasks such as email comprehension, itinerary planning, calendar synchronization, flight and hotel recommendations, itinerary sharing, and draft email generation.
The Counterintuitive Throughput Metrics
Industry convention often equates large parameter counts with high latency—but this test reveals a clear contradiction:
- Pre-fill throughput: >330 Token/s (critical for long prompt and batch request handling)
- Decode throughput: >28 Token/s (core metric for interactive fluidity)
Pre-fill throughput exceeding 330 Token/s means users experience near-zero wait time even with lengthy prompts, while 28 Token/s decode performance meets the baseline for practical interactive applications (typically 15-20 Token/s is sufficient for acceptable fluidity).
Adoption Recommendations: Who Should Try Now?
- Ready to try: Users of high-end flagship smartphones (equipped with sixth-gen Snapdragon 8 Supreme Edition), businesses requiring on-device processing for sensitive data due to privacy concerns
- Best to wait: Users of mid-tier devices (insufficient performance for full capability), applications demanding ultra-low latency for real-time voice interaction
- Developers: Can optimize prompt length and structure to match on-device inference characteristics, avoiding pre-fill delays from overly long context
Final Thoughts
The feasibility demonstration of deploying large MoE models on smartphones opens new pathways for low-latency, privacy-preserving agent applications. While real-world adoption hinges on device cost, power consumption, model reliability, and user acceptance, the journey of on-device large models from concept to practical application has taken a decisive step forward.