Core Event: Super-Node and Megakernel Approaches Break Through Trillion-Parameter Inference
In late September 2026, domestic and overseas teams nearly simultaneously unveiled inference optimization solutions targeting the world’s largest open-weight model, Kimi K3, marking the efficiency competitionfor large models has entered a deep phase at the system level:
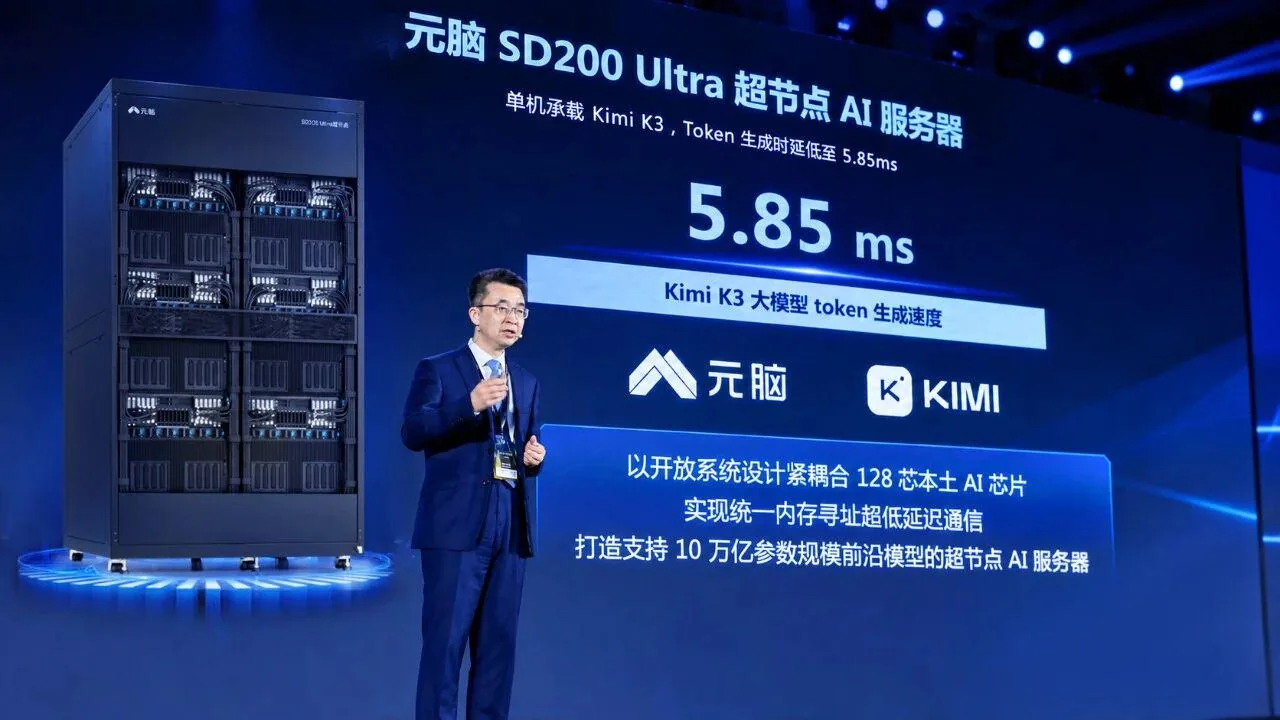
- Sept 21, 2026: Inspur released the Metacore SD200 Ultra super-node AI server, single-machine deploying the 2.8T-parameter Kimi K3, with token generation latency突破 5.85ms
- Sept 23, 2026: Overseas inference optimization team Inferact open-sourced tpu-megakernels, using 16 Google TPU v7 chips to fit the entire K3 model within a single kernel
- Kimi K3 officially recommends 64+ chips for deployment; unoptimized initial performance is ~10 tokens/s
- Inspur’s measured token latency: 5.85ms, single-user throughput: 170 tokens/s; Inferact’s low-concurrency decode throughput: 709 tokens/s
Operator Fusion: Breaking Kernel Boundaries to Address Memory Bottlenecks
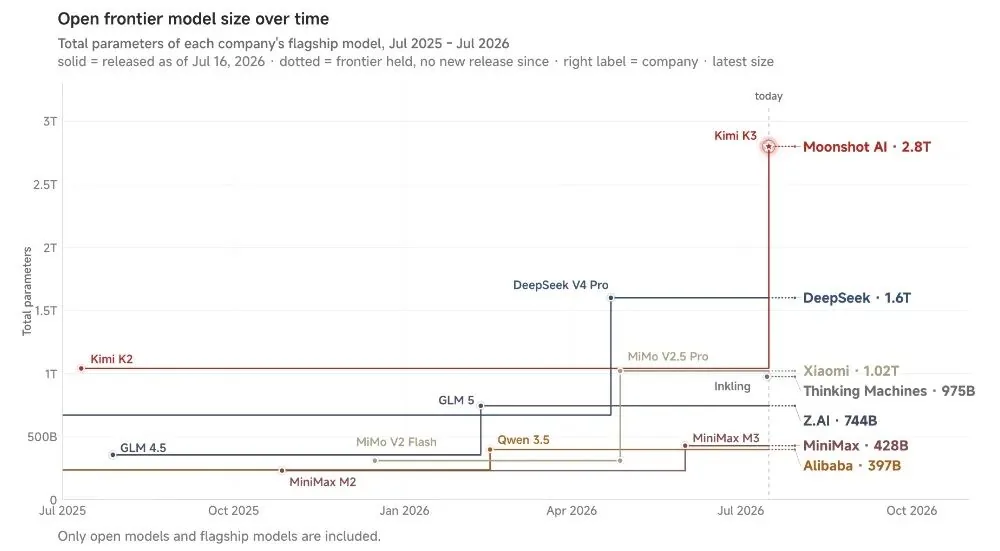
Kimi K3’s 2.8T total parameters and 104B activated parameters require ~1.5TB HBM bandwidth per forward pass, triggering over 120 All-to-All communications. Traditional inference frameworks suffer"bubble" delays from excessive fragmented kernel launches.
A counterintuitive contrast:
- Inferact’s overseas team chose extreme fusion: one megakernel for the entireDecode process, leveraging TPU v7’s 64 MiB on-chip VMEM for explicit data lifetime control, overlapping computation with data prefetching
- Inspur adopted an engineering-pragmatic approach: fusing numerous base operators into super-operators, reducing operator count by 10x, with communication-computation synchronized pipelines delivering 3x+ performance gains
Both paths converge on one truth: the traditional “one Op, one Kernel” loose coupling model has hit its ceiling; system-level fusion has become the new bottleneck breakthrough.
Super-Node System Battle: Three Breakthroughs from 128-Chip Tight Coupling
Inspur’s SD200 Ultra builds system-level advantages with three core innovations:
- 3D Hyper Mesh Interconnect: Tight coupling of 128 domestic AI chips, communication latency as low as 0.69μs
- Unified Address Space for GPU Memory: 8TB unified GPU memory and 64TB system RAM, with symmetry memory technology enabling the first GPU memory direct-connect on domestic chip super-nodes, achieving 3.5x faster AllReduce
- Super-Operator Agent: Kimi K3 itself participates in optimization—the agent generates tile-level pipeline super-operators for the K3 model, delivering 50% further performance boost over manual optimization via a “K3 optimizes K3” feedback loop
Paradigm Shift in Inference Optimization: AI as an Optimization Tool
Inspur’s “super-operator agent” transforms the model from an optimization target into an optimization tool itself, summarized by the high-speed rail vs. green-slot train analogy:
- Traditional approach: Hundreds of operators chaining sequentially, repeatedly writing intermediate results to HBM
- Super-operators: Results directly stay in registers/on-chip caches for next operators, implementing prefetch-compute-writeback as a three-stage concurrent pipeline
This paradigm significantly reduces manual optimization burden, enabling sustainable system-level efficiency iterations.
Adoption Guidance
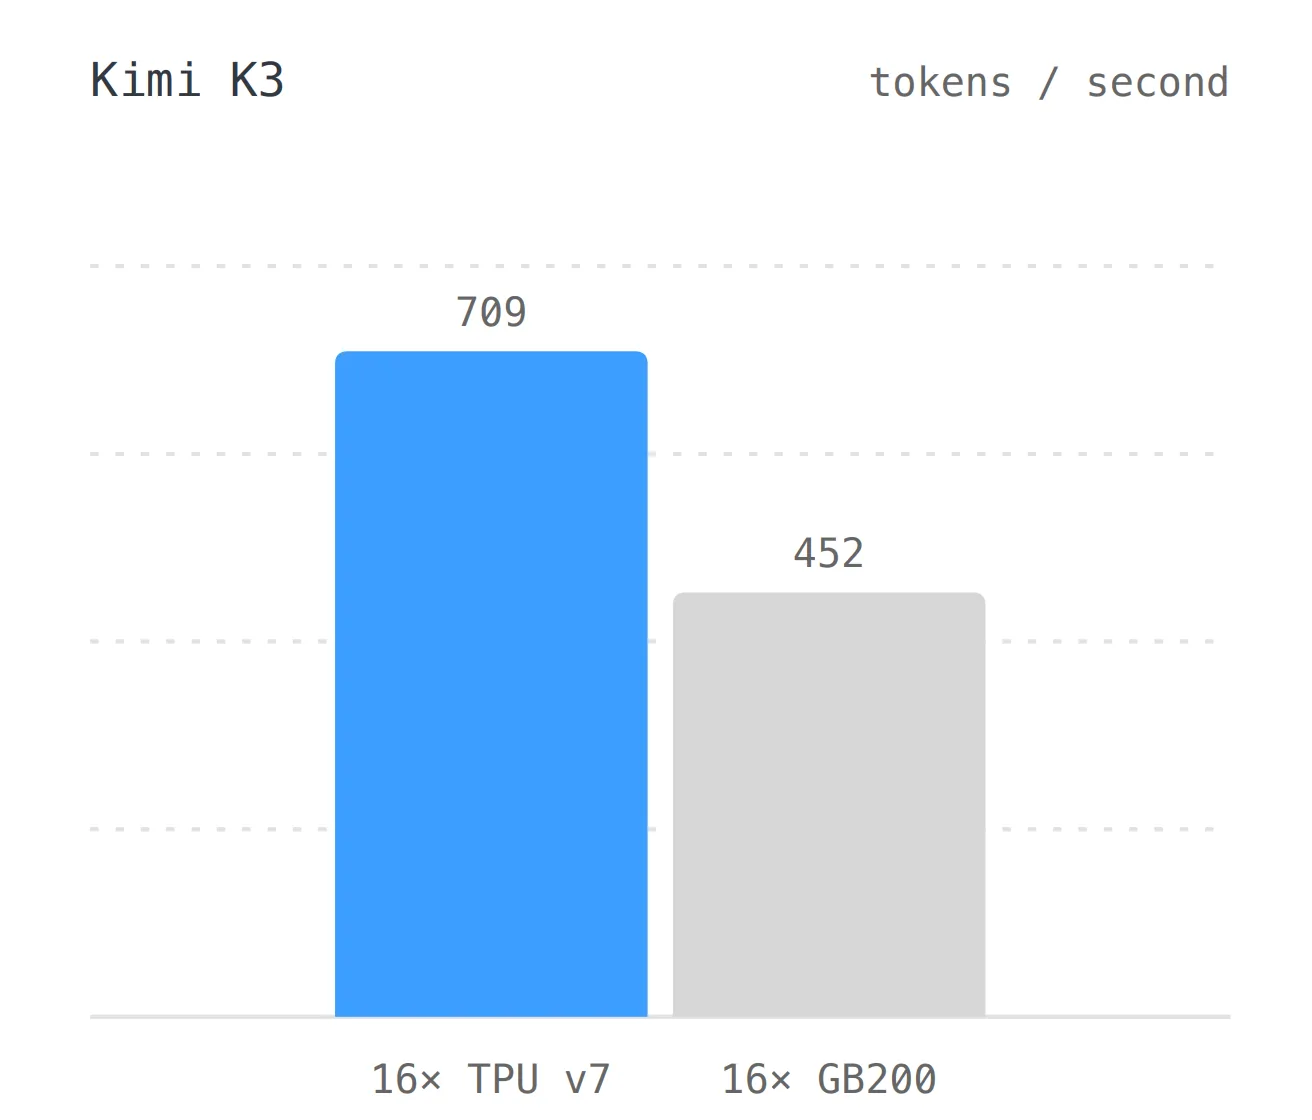
- Megakernel users (DSPark+tpu-megakernels): Teams with TPU v7 hardware seeking ultra-low decode latency—open-source tpu-megakernels Enable rapid prototyping
- SD200 Ultra super-node adopters: Commercial deployments requiring stable 2.8T-parameter model inference with国产化 requirements, prioritizing unified memory addressing and guaranteed system throughput
- Waiting recommended for: Buyers seeking maximum single-chip performance should monitor domestic chip ground-up capabilities; current super-node solutions still face single-chip performance ceilings
Final Thoughts
As AI compute competition shifts from chip specifications to system organization, Chinese teams have forged a deterministic追赶 path under chip-technology constraints via super-node and super-operator innovations. The convergence of megakernel and super-operator approaches confirms the inference efficiency revolutionhas decisively moved from model layer to system layer deep water.